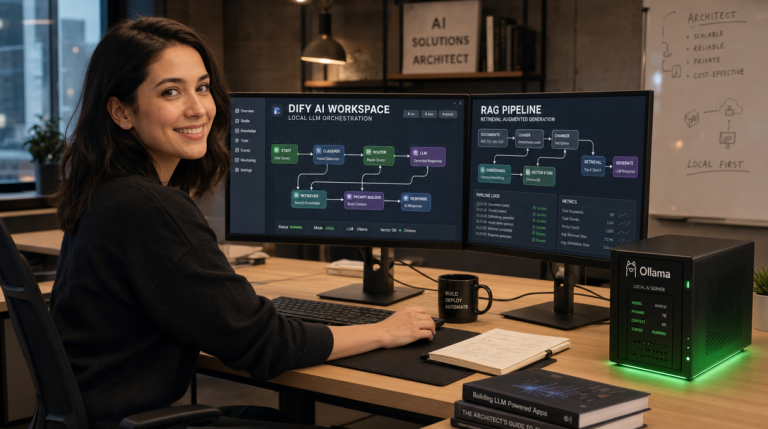
How to Deploy Qdrant Vector Database with Docker Compose and Ollama for Fast Local Semantic Search
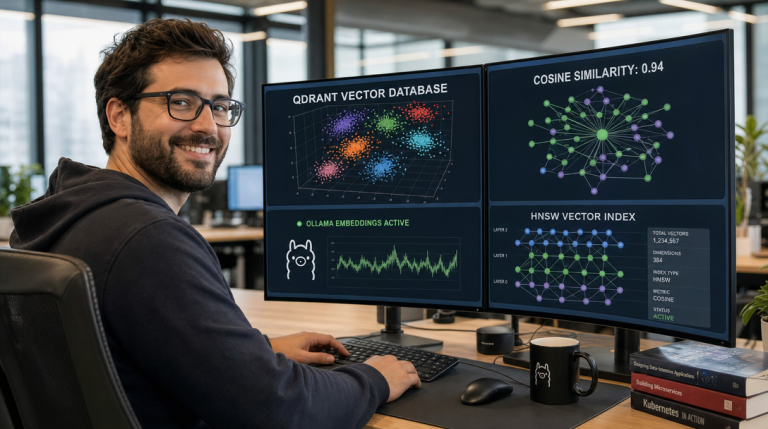
Traditional full-text search engines and relational databases rely on exact keyword matches, token stemming, and inverted indexes (such as BM25). While effective for finding specific terms or identifiers, traditional search fails completely when users query by concept, intent, or synonymous…