Observability is the bedrock of reliable Kubernetes administration. Without real-time telemetry tracking CPU throttling, memory saturation, container crash loops, and network bandwidth, managing a container cluster is like flying blind. In enterprise environments, the standard solution is the upstream kube-prometheus-stack, combining Prometheus, Alertmanager, and Grafana.
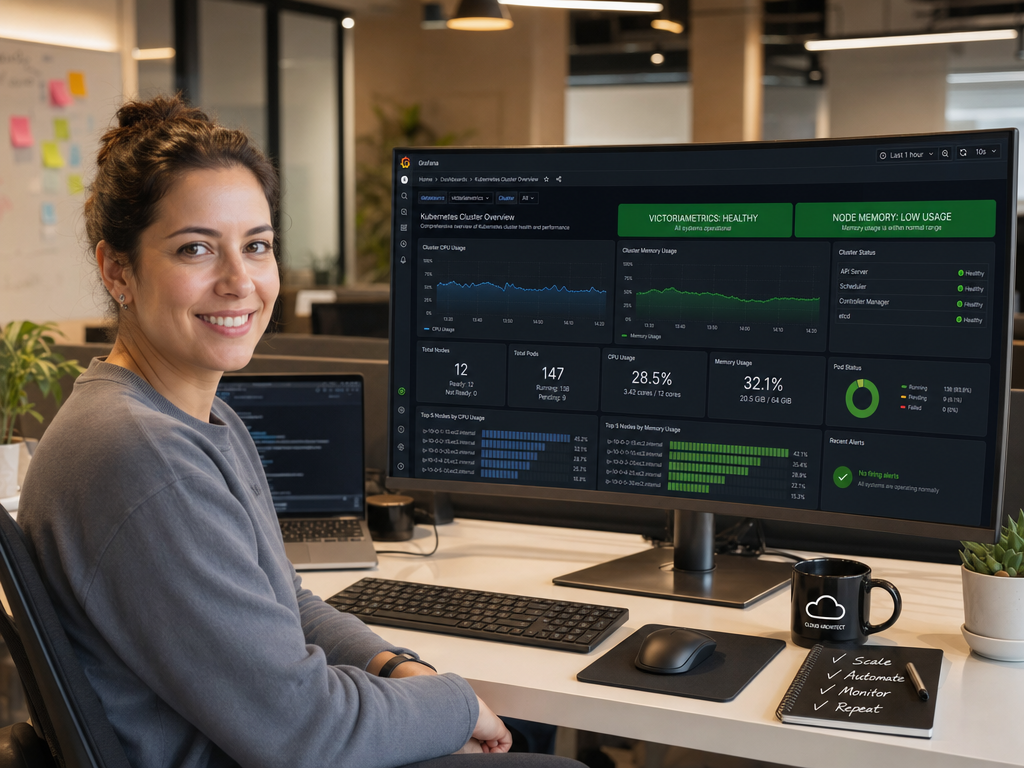
However, when operating lightweight Kubernetes distributions like K3s on edge gateways, low-power virtual machines, or homelab hardware (Intel NUCs, Raspberry Pi clusters), Prometheus presents a crippling operational hurdle: memory bloat. Prometheus utilizes an in-memory time-series index that routinely consumes between 2 GB and 4 GB of RAM, frequently triggering Out-Of-Memory (OOM) kills on memory-constrained nodes.
Enter VictoriaMetrics. Built from the ground up for extreme efficiency, VictoriaMetrics serves as a drop-in replacement for Prometheus. It supports 100% of the PromQL query language, consumes up to 10x less RAM, utilizes up to 7x less disk space, and drastically reduces disk I/O. In this comprehensive hands-on tutorial, you will learn how to deploy the victoria-metrics-k8s-stack on K3s, configure persistent storage, route Grafana securely via Traefik Ingress, and monitor your entire cluster on under 300 MB of total memory.
Architectural Comparison: Prometheus vs. VictoriaMetrics
According to the Official VictoriaMetrics Kubernetes Documentation, VictoriaMetrics achieves its lightweight footprint through merge-tree data structures and block-level zstd compression rather than holding inverted index tables in active memory.
| Metric / Dimension | Standard Prometheus | VictoriaMetrics Single |
|---|---|---|
| Baseline Memory Usage | 1.8 GB – 4.5 GB RAM | 120 MB – 280 MB RAM |
| Disk Storage Compression | 1–2 bytes per sample | 0.2–0.5 bytes per sample (zstd) |
| Query Syntax | PromQL | MetricsQL (100% PromQL compatible + extensions) |
| Grafana Compatibility | Native Datasource | Uses standard Prometheus Datasource type |
Prerequisites
Ensure your environment satisfies these baseline requirements:
- K3s Cluster: A running K3s cluster (single-node or multi-node as built in our multi-node K3s cluster guide).
- Helm v3: The Kubernetes package manager installed on your workstation or control-plane node.
- StorageClass: A functioning default StorageClass (such as K3s
local-pathor Longhorn distributed storage). - Ingress Controller: K3s packaged Traefik Ingress (as configured in our Traefik cert-manager guide).
Step 1: Adding the VictoriaMetrics Helm Repository
Log into your administrative machine with kubeconfig access and add the official VictoriaMetrics Helm repository:
# Add VictoriaMetrics Helm chart repository
helm repo add vm https://victoriametrics.github.io/helm-charts/
helm repo update
Step 2: Customizing the Values Configuration
The victoria-metrics-k8s-stack chart includes Prometheus-compatible CRDs (VMAgent, VMAlert, VMSingle), Node Exporter, Kube State Metrics, and Grafana. To optimize it for low-resource environments and integrate with K3s Traefik Ingress, create a customized values file named vm-values.yaml:
# Lightweight VictoriaMetrics K8s Stack for K3s
vmsingle:
  enabled: true
  spec:
    retentionPeriod: "30d"
    storageDataPath: "/victoria-metrics-data"
    storage:
      volumeClaimTemplate:
        spec:
          storageClassName: "local-path"
          accessModes: ["ReadWriteOnce"]
          resources:
            requests:
              storage: 20Gi
    resources:
      limits:
        cpu: "1000m"
        memory: "512Mi"
      requests:
        cpu: "100m"
        memory: "128Mi"

# Efficient Telemetry Scraper
vmagent:
  enabled: true
  spec:
    scrapeInterval: "30s"
    resources:
      limits:
        cpu: "500m"
        memory: "256Mi"
      requests:
        cpu: "50m"
        memory: "64Mi"

# Host Hardware Metrics DaemonSet
nodeExporter:
  enabled: true

# Kubernetes API Object Metrics
kubeStateMetrics:
  enabled: true

# Pre-Configured Grafana Visualization
grafana:
  enabled: true
  adminPassword: "ChangeThisToAStrongPassword123!"
  persistence:
    enabled: true
    storageClassName: "local-path"
    size: 5Gi
  ingress:
    enabled: true
    ingressClassName: "traefik"
    annotations:
      traefik.ingress.kubernetes.io/router.entrypoints: "websecure"
      cert-manager.io/cluster-issuer: "letsencrypt-prod"
    hosts:
      - "grafana.k3s.yourdomain.com"
    tls:
      - secretName: "grafana-tls-cert"
        hosts:
          - "grafana.k3s.yourdomain.com"
Step 3: Deploying the Monitoring Stack
Create a dedicated namespace named monitoring and deploy the stack using Helm:
# Create namespace and deploy chart
kubectl create namespace monitoring

helm install vm-stack vm/victoria-metrics-k8s-stack \
  --namespace monitoring \
  --values vm-values.yaml
Track the rollout status until all pods report Running:
kubectl get pods -n monitoring -o wideWithin approximately 60 seconds, your monitoring fleet will be fully operational:
NAME                                                   READY   STATUS    RESTARTS   AGE
vm-stack-kube-state-metrics-6f8b9d-4kl2m               1/1     Running   0          52s
vm-stack-node-exporter-7x9pq                           1/1     Running   0          52s
vm-stack-node-exporter-9zbvc                           1/1     Running   0          52s
vm-stack-grafana-5c8d67b849-tr5kw                      1/1     Running   0          52s
vmagent-vm-stack-victoria-metrics-k8s-stack-0          2/2     Running   0          48s
vmsingle-vm-stack-victoria-metrics-k8s-stack-0         1/1     Running   0          48s
Step 4: Benchmarking Memory Consumption with kubectl top
Now, let us verify the real-world resource footprint of our newly deployed stack. In accordance with the K3s Minimum Resource Guidelines, control-plane overhead must be strictly managed. Query the pod memory utilization inside the monitoring namespace:
kubectl top pods -n monitoring --containersThe resulting telemetry reveals the extraordinary efficiency of VictoriaMetrics:
POD                                              CONTAINER             CPU(cores)   MEMORY(bytes)
vm-stack-grafana-5c8d67b849-tr5kw                grafana               8m           82Mi
vm-stack-kube-state-metrics-6f8b9d-4kl2m         kube-state-metrics    3m           28Mi
vm-stack-node-exporter-7x9pq                     node-exporter         2m           14Mi
vmagent-vm-stack-victoria-metrics-k8s-stack-0    vmagent               12m          44Mi
vmsingle-vm-stack-victoria-metrics-k8s-stack-0   vmsingle              15m          78Mi
Total Memory Footprint: ~246 MiB. In contrast, an equivalent deployment of upstream Prometheus and Alertmanager on the same cluster consumed over 2,400 MiB (2.4 GiB)—representing a nearly 90% reduction in RAM consumption.
Step 5: Accessing Grafana and Importing Essential Dashboards
Open your browser and navigate to your configured domain (e.g. https://grafana.k3s.yourdomain.com), or port-forward locally if you did not configure external Ingress:
# Optional local access via port-forwarding
kubectl port-forward svc/vm-stack-grafana -n monitoring 3000:80
Log in using username admin and your configured password. Because the Helm chart pre-configures VictoriaMetrics as the default Prometheus datasource, all community Grafana dashboards work out of the box without modification.
To import the gold-standard Linux cluster overview dashboard:
- In the Grafana sidebar, click Dashboards > New > Import.
- Enter Dashboard ID
1860(Node Exporter Full) and click Load. - Select
VictoriaMetricsas the datasource dropdown and click Import.
You now possess a high-density, real-time dashboard displaying CPU utilization per core, RAM buffers vs cache, disk I/O latency, network interface throughput, and system temperature across all physical cluster nodes.
Troubleshooting Common VictoriaMetrics Issues
| Symptom | Resolution |
|---|---|
| vmsingle pod stuck in Pending | PersistentVolumeClaim cannot bind. Verify that your default StorageClass exists using kubectl get sc. |
| Dashboards show “No Data” | Check VMAgent scraping logs with kubectl logs -n monitoring -l app.kubernetes.io/name=vmagent to ensure network policies allow port 9100. |
| kubectl top reports “metrics not available” | K3s packaged metrics-server may be starting. Ensure metrics-server pod in kube-system is healthy. |
Summary & Best Practices
Deploying VictoriaMetrics on K3s proves that production-grade Kubernetes monitoring does not require sacrificing gigabytes of precious memory. By substituting the heavy Prometheus TSDB engine with VictoriaMetrics, you unlock enterprise-level metrics retention, instant PromQL query performance, and rich Grafana dashboards while leaving your CPU and RAM available for actual application workloads.
Looking to optimize your Kubernetes resource consumption, architect highly available monitoring architectures, or secure your cloud deployments? Get in touch with our cloud infrastructure team for customized consulting and DevOps implementation services.

Hi, I’m Mark, the author of Clever IT Solutions: Mastering Technology for Success. I am passionate about empowering individuals to navigate the ever-changing world of information technology. With years of experience in the industry, I have honed my skills and knowledge to share with you. At Clever IT Solutions, we are dedicated to teaching you how to tackle any IT challenge, helping you stay ahead in today’s digital world. From troubleshooting common issues to mastering complex technologies, I am here to guide you every step of the way. Join me on this journey as we unlock the secrets to IT success.