Running local AI models with Ollama has revolutionized private inference. However, as organizations and engineering teams expand their usage, direct point-to-point connections between client applications and individual Ollama servers quickly hit operational bottlenecks. A single Ollama server can become saturated under concurrent prompt loads, lacks granular API key tracking, does not natively balance requests across multiple GPU worker nodes, and cannot automatically fall back to cloud providers when local compute is overwhelmed.
LiteLLM Proxy provides the missing enterprise gateway layer. Acting as an ultra-fast, OpenAI-compatible proxy, LiteLLM sits between your applications and multiple LLM backends. In this comprehensive guide, we will set up LiteLLM Proxy in Docker Compose, configure multi-node load balancing across local Ollama instances, implement automatic failover routing, and issue managed virtual API keys with usage quotas.
Why Use LiteLLM Proxy in Front of Ollama?
LiteLLM Proxy translates requests into the universal OpenAI API schema (/v1/chat/completions, /v1/embeddings, /v1/models). Integrating it into your homelab or private enterprise infrastructure delivers several core benefits:
- Load Balancing Across GPU Nodes: Distribute concurrent inference requests across multiple Ollama servers using round-robin, least-busy, or latency-based routing.
- Automatic Failovers & Cooldowns: If an Ollama node runs out of VRAM (CUDA OOM error) or loses network connectivity, LiteLLM automatically retries the request against a secondary node or fallback model.
- Virtual API Key Management: Create scoped API keys with rate limits (RPM/TPM), budget caps (max spend/tokens), and model access whitelists.
- Drop-in Application Compatibility: Any software built for OpenAI (LibreChat, Open-WebUI, Cursor, LangChain, AutoGen) connects to your self-hosted models by simply updating the
OPENAI_BASE_URL. - Detailed Audit & Telemetry Logging: Track request latencies, token consumption, and errors with Prometheus metrics, OpenTelemetry, or PostgreSQL storage.
Architecture: The LiteLLM Gateway Pattern
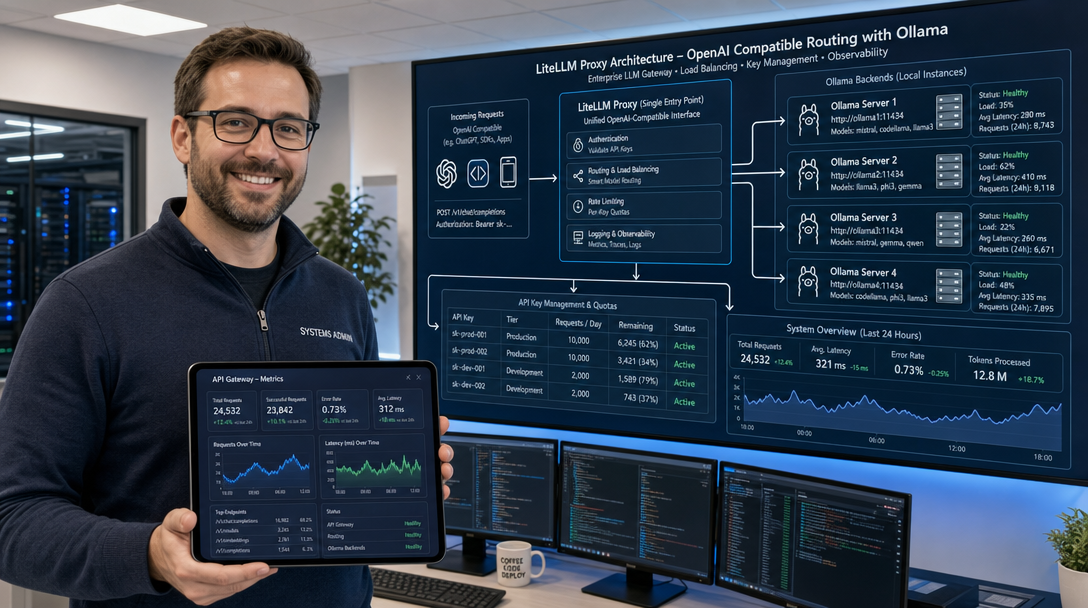
The diagram below demonstrates how client traffic flows through LiteLLM Proxy to distributed Ollama inference instances:
+--------------------------------------------------------------------+
|                         Client Layer                               |
|       (Open-WebUI / Coding Agents / Internal Microservices)        |
+--------------------------------------------------------------------+
                                   |
                                   | HTTP / HTTPS (Bearer Token Auth)
                                   v
+--------------------------------------------------------------------+
|                     LiteLLM Proxy (Port 4000)                      |
|                                                                    |
|  - Virtual Key Validation & Rate Limiting                         |
|  - Load Balancer & Health Checks (Cooldown Tracking)               |
|  - Unified OpenAI Schema Translator                                |
+--------------------------------------------------------------------+
              |                                        |
              | Internal Docker Bridge / LAN           |
              v                                        v
+-----------------------------+          +---------------------------+
|    Ollama Node A (Local)    |          |   Ollama Node B (Remote)  |
|  http://ollama-a:11434      |          |  http://192.168.1.50:11434|
|  (NVIDIA RTX 4090 - GPU 0)  |          |  (NVIDIA RTX 3090 - GPU 1)|
+-----------------------------+          +---------------------------+
Step 1: Preparing Directory Structure and Database
LiteLLM Proxy utilizes PostgreSQL to persist user keys, spend tracking, and audit logs. Create a dedicated project directory:
mkdir -p ~/litellm-docker/config ~/litellm-docker/pgdata
cd ~/litellm-docker
Create an environment file .env with secure secrets:
cat <<EOF > .env
LITELLM_MASTER_KEY=sk-$(openssl rand -hex 16)
POSTGRES_USER=litellm
POSTGRES_PASSWORD=$(openssl rand -hex 16)
POSTGRES_DB=litellm
EOF
Step 2: Defining the LiteLLM Configuration (config.yaml)
The core routing logic is defined in config/config.yaml. Here, we register a virtual model identifier (llama-3-fleet) backed by two distinct Ollama instances with weighted load balancing and automatic cooldowns:
model_list:
  # Primary Model Group with Load Balancing
  - model_name: llama-3-fleet
    litellm_params:
      model: ollama/llama3.1:8b
      api_base: http://ollama:11434
      rpm: 60
    model_info:
      id: "node-local"

  - model_name: llama-3-fleet
    litellm_params:
      model: ollama/llama3.1:8b
      # Example of a secondary server on your local LAN
      api_base: http://192.168.1.50:11434
      rpm: 60
    model_info:
      id: "node-worker"

  # Fallback Model: Smaller model if primary fleet is overloaded
  - model_name: fallback-fast
    litellm_params:
      model: ollama/qwen2.5:3b
      api_base: http://ollama:11434

router_settings:
  routing_strategy: "least-busy" # Options: simple-shuffle, least-busy, usage-based-routing
  model_group_alias:
    "gpt-4o-mini": "llama-3-fleet" # Transparently redirect cloud requests to local hardware
  cooldown_time: 30 # Seconds to wait before retrying an unhealthy endpoint
  num_retries: 3
  timeout: 120

general_settings:
  master_key: os.environ/LITELLM_MASTER_KEY
  database_url: os.environ/DATABASE_URL
Step 3: Docker Compose Deployment
Now, create docker-compose.yml to run LiteLLM Proxy, PostgreSQL, and a local Ollama container in an integrated stack:
services:
  ollama:
    image: ollama/ollama:latest
    container_name: ollama
    restart: unless-stopped
    ports:
      - "127.0.0.1:11434:11434"
    volumes:
      - ollama_models:/root/.ollama
    # GPU acceleration (remove deploy block if running CPU-only)
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: all
              capabilities: [gpu]
    networks:
      - gateway_net

  postgres:
    image: postgres:16-alpine
    container_name: litellm-postgres
    restart: unless-stopped
    environment:
      POSTGRES_USER: ${POSTGRES_USER}
      POSTGRES_PASSWORD: ${POSTGRES_PASSWORD}
      POSTGRES_DB: ${POSTGRES_DB}
    volumes:
      - ./pgdata:/var/lib/postgresql/data
    networks:
      - gateway_net

  litellm:
    image: ghcr.io/berriai/litellm:main-latest
    container_name: litellm-proxy
    restart: unless-stopped
    depends_on:
      - postgres
      - ollama
    ports:
      - "0.0.0.0:4000:4000"
    environment:
      - LITELLM_MASTER_KEY=${LITELLM_MASTER_KEY}
      - DATABASE_URL=postgresql://${POSTGRES_USER}:${POSTGRES_PASSWORD}@postgres:5432/${POSTGRES_DB}
      - STORE_MODEL_IN_DB=True
    volumes:
      - ./config/config.yaml:/app/config.yaml
    command: ["--config", "/app/config.yaml", "--port", "4000", "--num_workers", "4"]
    networks:
      - gateway_net

networks:
  gateway_net:
    name: gateway_net
    driver: bridge

volumes:
  ollama_models:
    name: ollama_models
Step 4: Launching and Testing the Proxy
Start the services:
docker compose up -d
Pull the required model in Ollama:
docker exec -it ollama ollama pull llama3.1:8b
docker exec -it ollama ollama pull qwen2.5:3b
Retrieve your Master Key from the .env file:
grep LITELLM_MASTER_KEY .env
Send a standard OpenAI-compatible test request to port 4000:
curl -X POST http://localhost:4000/v1/chat/completions \
  -H "Content-Type: application/json" \
  -H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" \
  -d '{
    "model": "llama-3-fleet",
    "messages": [
      {"role": "user", "content": "Explain what a reverse proxy does in 2 sentences."}
    ],
    "temperature": 0.7
  }'
Step 5: Generating Managed Virtual Keys
Instead of distributing your master admin key, generate individual virtual API keys with defined token limits and model restrictions via LiteLLM’s management API:
curl -X POST http://localhost:4000/key/generate \
  -H "Authorization: Bearer YOUR_LITELLM_MASTER_KEY" \
  -H "Content-Type: application/json" \
  -d '{
    "models": ["llama-3-fleet"],
    "duration": "30d",
    "max_budget": 0.0,
    "rpm_limit": 30,
    "metadata": {"team": "frontend-devs"}
  }'
The response returns a scoped key (starting with sk-...) that you can safely distribute to team members or third-party web apps.
Production Hardening Checklist
- Reverse Proxy with TLS: Place Caddy or Nginx in front of port 4000 to enforce HTTPS and prevent plain-text bearer token transmission over the network.
- Set Worker Concurrency: Tune the
--num_workersflag based on your CPU core count to handle high-concurrency client polling. - Monitor Ollama VRAM: Ollama will queue incoming requests if VRAM is fully allocated. Use
least-busyrouting in LiteLLM so new requests automatically route to underutilized GPU workers.
Conclusion
Deploying LiteLLM Proxy transforms isolated local Ollama instances into an elastic, resilient, and manageable AI gateway. You achieve the operational control of public cloud AI APIs—including load balancing, telemetry, and scoped authentication—while retaining the privacy and cost-efficiency of self-hosted open-source models.

Hi, I’m Mark, the author of Clever IT Solutions: Mastering Technology for Success. I am passionate about empowering individuals to navigate the ever-changing world of information technology. With years of experience in the industry, I have honed my skills and knowledge to share with you. At Clever IT Solutions, we are dedicated to teaching you how to tackle any IT challenge, helping you stay ahead in today’s digital world. From troubleshooting common issues to mastering complex technologies, I am here to guide you every step of the way. Join me on this journey as we unlock the secrets to IT success.