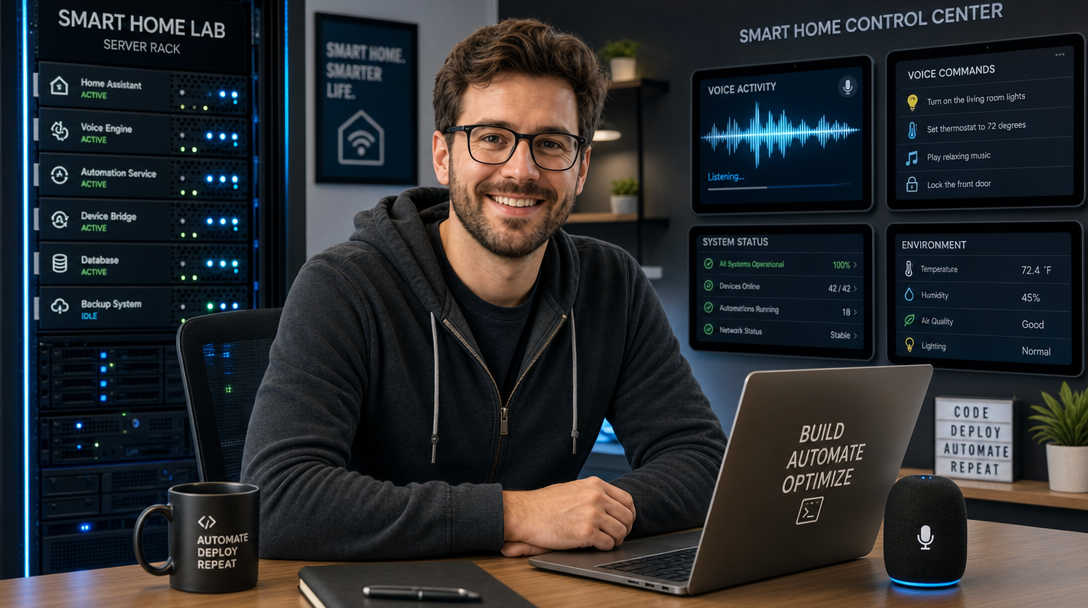
Commercial smart speakers like Amazon Echo and Google Nest offer voice convenience at a steep cost: your ambient conversations and acoustic telemetry are continuously streamed to third-party corporate servers. Furthermore, whenever cloud providers adjust API pricing, retire hardware generations, or experience regional internet outages, your voice-controlled smart home grinds to an immediate halt.
By leveraging open-source components—specifically Home Assistant, Faster-Whisper, Piper TTS, and OpenWakeWord—you can build an entirely local, zero-cloud voice assistant running inside lightweight Docker containers. The glue binding these microservices is the Wyoming Protocol: an open, asynchronous network protocol developed by Nabu Casa that standardizes voice satellite communication, audio streaming, speech-to-text (STT), text-to-speech (TTS), and local wake-word detection.
In this comprehensive architectural guide, we will deploy a fully self-hosted voice processing pipeline using Docker Compose, integrate it directly into Home Assistant Assist, and optimize inference models for low-latency, sub-second voice execution on standard homelab hardware.
Architecture: The Wyoming Voice Pipeline
A resilient voice assistant requires distinct computational stages: wake-word recognition, acoustic speech transcription, intent parsing, action execution, and acoustic synthesis. Isolating these capabilities into modular containerized services prevents monolithic bottlenecks and allows independent scaling or GPU acceleration.
+-----------------------------------------------------------------------------+
|                               Local Homelab LAN                             |
|                                                                             |
|  [Voice Satellite / Mic] (ESP32-S3 Box / Wyoming Satellite)                 |
|            |                                                                |
|            | (Raw PCM Audio via UDP / TCP)                                  |
|            v                                                                |
|  +-----------------------------------------------------------------------+  |
|  | Container: openwakeword (Port 10400)                                  |  |
|  | Continuous Stream Analysis -> Detects "Hey Jarvis" / "Okay Nabu"      |  |
|  +-----------------------------------+-----------------------------------+  |
|                                      | Trigger Event                        |
|                                      v                                      |
|  +-----------------------------------------------------------------------+  |
|  | Container: homeassistant (Port 8123) - Assist Engine                  |  |
|  | Orchestrates Pipeline & Intent Matching                              |  |
|  +-------------------+-------------------------------+-------------------+  |
|                      |                               ^                      |
|       Speech Stream  |                Spoken Output  |                      |
|             (Audio)  v                       (Audio) |                      |
|  +---------------------------+   +---------------------------+              |
|  | Container: faster-whisper |   | Container: piper          |              |
|  | (Port 10300)              |   | (Port 10200)              |              |
|  | Speech-to-Text (STT)      |   | Text-to-Speech (TTS)      |              |
|  | Engine: CTranslate2       |   | Ultra-fast ONNX Synthesis |              |
|  +---------------------------+   +---------------------------+              |
+-----------------------------------------------------------------------------+
Component Breakdown
- Home Assistant Assist: The central orchestrator handling conversation agents, device state registries, and entity commands (e.g., turning on relays or adjusting climate).
- Wyoming OpenWakeWord: Continuously analyzes streaming audio buffers using compact tflite models, triggering the pipeline only when the target wake-phrase is identified with high statistical confidence.
- Wyoming Faster-Whisper: Utilizes
CTranslate2, a fast inference engine for Transformer models, executing quantized OpenAI Whisper weights up to 4x faster than vanilla PyTorch with significantly reduced memory footprint. - Wyoming Piper: A lightning-fast, high-quality local neural text-to-speech system optimized for Raspberry Pi and x86_64 CPUs, generating natural audio streams with near-zero initial latency.
Prerequisites & Hardware Sizing
Before launching the stack, verify that your host system satisfies the hardware requirements for real-time acoustic processing:
- CPU: 4 cores modern x86_64 (Intel 8th Gen+ / AMD Ryzen) or ARM64 (Raspberry Pi 5 with active cooling). AVX2 instruction support is critical for fast CTranslate2 CPU inference.
- RAM: 4 GB minimum dedicated to voice services (8 GB recommended if running the
medium.enWhisper model). - Storage: 15 GB NVMe or SSD storage for container images and cached ONNX/int8 model weights.
- Operating System: Debian 12 / Ubuntu 24.04 LTS with Docker Engine 26+ and Docker Compose v2.
Step 1: Directory Structure and Pre-Configuration
We will construct an isolated filesystem structure under /opt/local-voice to persist models, user configurations, and Home Assistant state data.
sudo mkdir -p /opt/local-voice/{ha-config,whisper-data,piper-data,openwakeword-data}
sudo chown -R 1000:1000 /opt/local-voice
cd /opt/local-voice
Setting ownership ensures that containers running under non-root identifiers can write cached model files without permission conflicts.
Step 2: Production Docker Compose Configuration
Create the docker-compose.yml file containing Home Assistant and the three Wyoming microservices. In this configuration, we bind services to an isolated internal Docker network while exposing the necessary Wyoming RPC ports for Home Assistant integration.
services:
  homeassistant:
    image: ghcr.io/home-assistant/home-assistant:2026.9.3
    container_name: homeassistant
    restart: unless-stopped
    privileged: true
    network_mode: host
    environment:
      - TZ=Etc/UTC
    volumes:
      - /opt/local-voice/ha-config:/config
      - /etc/localtime:/etc/localtime:ro
      - /run/dbus:/run/dbus:ro
    depends_on:
      - faster-whisper
      - piper
      - openwakeword

  faster-whisper:
    image: rhasspy/wyoming-whisper:latest
    container_name: wyoming-whisper
    restart: unless-stopped
    ports:
      - "10300:10300"
    volumes:
      - /opt/local-voice/whisper-data:/data
    environment:
      - TZ=Etc/UTC
    command:
      - --model
      - small-int8
      - --language
      - en
      - --data-dir
      - /data
      - --download-dir
      - /data
      - --beam-size
      - "1"
    deploy:
      resources:
        limits:
          memory: 3500M
          cpus: '3.0'

  piper:
    image: rhasspy/wyoming-piper:latest
    container_name: wyoming-piper
    restart: unless-stopped
    ports:
      - "10200:10200"
    volumes:
      - /opt/local-voice/piper-data:/data
    environment:
      - TZ=Etc/UTC
    command:
      - --voice
      - en_US-lessac-medium
      - --data-dir
      - /data
      - --download-dir
      - /data
    deploy:
      resources:
        limits:
          memory: 1000M
          cpus: '2.0'

  openwakeword:
    image: rhasspy/wyoming-openwakeword:latest
    container_name: wyoming-openwakeword
    restart: unless-stopped
    ports:
      - "10400:10400"
    volumes:
      - /opt/local-voice/openwakeword-data:/data
    environment:
      - TZ=Etc/UTC
    command:
      - --preload-model
      - ok_nabu
      - --preload-model
      - hey_jarvis
      - --data-dir
      - /data
    deploy:
      resources:
        limits:
          memory: 800M
          cpus: '1.5'
Configuration Deep-Dive
--model small-int8: The 8-bit quantizedsmallWhisper model delivers the sweet spot between contextual transcription accuracy and CPU inference speed (~350ms for a typical 3-second utterance on x86_64).--beam-size 1: Greedy decoding significantly reduces CPU cycle utilization compared to beam size 5, yielding real-time transcription without perceptible degradation on home automation commands.--voice en_US-lessac-medium: The Lessac medium voice is exceptionally natural, clear, and executes with an audio real-time factor (RTF) well below 0.15 on CPU.--preload-model ok_nabu: Ensures the wake-word neural weights are resident in RAM, eliminating initialization delays on incoming satellite audio streams.network_mode: hostfor Home Assistant: Essential for auto-discovering UPnP, mDNS, Matter, and local audio hardware across your physical local area network.
Step 3: Deploying the Container Stack
Deploy the stack in detached mode using Docker Compose:
docker compose up -dMonitor the initial startup logs to verify model downloads and socket listeners:
docker compose logs -f faster-whisper piper openwakewordYou should see confirmation output indicating that the models have downloaded and the Wyoming RPC sockets are listening:
wyoming-whisper      | INFO:root:Downloading model small-int8 to /data...
wyoming-whisper      | INFO:root:Ready. Listening on 0.0.0.0:10300
wyoming-piper        | INFO:root:Downloading voice en_US-lessac-medium...
wyoming-piper        | INFO:root:Ready. Listening on 0.0.0.0:10200
wyoming-openwakeword | INFO:root:Loaded model ok_nabu
wyoming-openwakeword | INFO:root:Ready. Listening on 0.0.0.0:10400
Step 4: Connecting Wyoming Microservices in Home Assistant
Once the containers are active, navigate to your Home Assistant dashboard at http://<your-server-ip>:8123 and connect each Wyoming service individually:
1. Open Settings > Devices & Services > Add Integration.
2. Search for Wyoming Protocol and click to add.
3. Add the three services using your host IP (or 127.0.0.1 since Home Assistant is running in host network mode):
- Faster-Whisper: Host
127.0.0.1| Port10300 - Piper TTS: Host
127.0.0.1| Port10200 - OpenWakeWord: Host
127.0.0.1| Port10400
Home Assistant will immediately detect the exposed capabilities and register them under the Speech-to-Text, Text-to-Speech, and Wake Word provider registries.
Step 5: Configuring the Custom Voice Assistant Pipeline
Now we combine the modular microservices into an active execution pipeline:
1. In Home Assistant, navigate to Settings > Voice Assistants > Add Assistant.
2. Configure the pipeline parameters:
- Name:
Local Private Voice (Wyoming) - Language:
English (en) - Conversation Agent:
Home Assistant(Local intent matching) - Speech-to-Text:
faster-whisper(small-int8) - Text-to-Speech:
piper(en_US-lessac-medium) - Wake Word:
openWakeWord> selectOkay NabuorHey Jarvis
3. Under Advanced Settings, calibrate the Silence Detection timeout to 1.2 seconds to balance natural pauses against responsive turnaround times.
4. Save the configuration and set this pipeline as your default.
Step 6: Testing with Browser Audio & Voice Satellites
To verify end-to-end functionality without physical satellite hardware:
1. Open Home Assistant in a modern desktop browser supporting WebRTC / Audio capture.
2. Click the Assist icon in the top right menu bar.
3. Click the microphone icon, say “Turn on the office light” or “What time is it?”, and observe the sub-second transcription and Piper spoken response.
For dedicated hardware voice satellites, you can flash an ESP32-S3 Box 3 or run Wyoming-Satellite on a Raspberry Pi Zero 2W with a USB microphone array, pointing audio packets directly to your server’s IP address.
Security Hardening & Production Best Practices
1. Restrict Network Exposure
Wyoming protocol endpoints do not incorporate authentication headers by default. If your host is exposed to multi-tenant or untrusted networks, bind Wyoming ports strictly to localhost or private VLAN interfaces using UFW (Uncomplicated Firewall):
sudo ufw default deny incoming
sudo ufw allow 22/tcp
sudo ufw allow 8123/tcp
sudo ufw allow from 192.168.1.0/24 to any port 10200 proto tcp
sudo ufw allow from 192.168.1.0/24 to any port 10300 proto tcp
sudo ufw allow from 192.168.1.0/24 to any port 10400 proto tcp
sudo ufw enable
2. Dedicated Storage & Cache Isolation
Wyoming containers store neural network weights locally. Mounting persistent host paths prevents the images from re-downloading hundreds of megabytes of weight files upon container recreation or reboots.
3. Optional GPU Acceleration with NVIDIA Container Toolkit
If your homelab server includes a discrete NVIDIA GPU (e.g., GTX 1650, RTX 3060, or Tesla T4), you can unlock near-instantaneous transcription by running Whisper on CUDA cores:
  faster-whisper:
    image: rhasspy/wyoming-whisper:latest
    deploy:
      resources:
        reservations:
          devices:
            - driver: nvidia
              count: all
              capabilities: [gpu]
    command:
      - --model
      - medium-int8
      - --device
      - cuda
Troubleshooting Common Operational Issues
Issue 1: High Transcription Latency or Stuttering Audio
Symptom: Speech transcription takes 3 to 6 seconds after speaking, making voice control sluggish.
Root Cause: The Whisper model is too large for the host CPU, or floating-point calculations are running without int8 quantization.
Resolution: Downgrade the model from medium to small-int8 or base-int8 in docker-compose.yml. Ensure --beam-size 1 is set in the execution flags. Check CPU utilization with docker stats wyoming-whisper to ensure no throttling is occurring.
Issue 2: OpenWakeWord False Positives or Unresponsive Detection
Symptom: The voice assistant frequently activates randomly from background conversation or fails to trigger when speaking clearly.
Root Cause: Suboptimal microphone input gain or wake-word detection threshold mismatch.
Resolution: In Home Assistant, open Settings > Devices & Services > Wyoming Protocol (openWakeWord) > Configure. Adjust the probability threshold to 0.6 for balanced sensitivity. If using an ESP32 voice satellite, enable hardware acoustic echo cancellation (AEC) and noise suppression (NS) in your ESPHome configuration.
Issue 3: Piper TTS Output Audio Truncation
Symptom: The first or last syllable of spoken responses is cut off on satellite speakers.
Root Cause: Audio output buffer underflow or aggressive media player auto-sleep timers on the playback device.
Resolution: Set an audio lead-in and lead-out silence buffer in Home Assistant Assist settings, or append 50ms of trailing silence in the voice satellite firmware.
Conclusion: True Sovereignty for Voice Automation
Deploying a private voice assistant using Faster-Whisper, Piper, and OpenWakeWord delivers the ultimate combination of speed, reliability, and privacy. Commands execute in milliseconds directly on your local network, with zero external dependencies and zero risk of vendor lock-in or acoustic surveillance.
To take your homelab further, consider integrating a local Large Language Model via Ollama as an intelligent fallback conversation agent in Home Assistant Assist. When Home Assistant encounters a query that does not map to a physical entity (such as “Why is the sky blue?” or “Suggest a recipe for dinner”), Assist seamlessly forwards the request to your local LLM, providing a fully sovereign, multimodal artificial intelligence ecosystem.

Hi, I’m Mark, the author of Clever IT Solutions: Mastering Technology for Success. I am passionate about empowering individuals to navigate the ever-changing world of information technology. With years of experience in the industry, I have honed my skills and knowledge to share with you. At Clever IT Solutions, we are dedicated to teaching you how to tackle any IT challenge, helping you stay ahead in today’s digital world. From troubleshooting common issues to mastering complex technologies, I am here to guide you every step of the way. Join me on this journey as we unlock the secrets to IT success.