In containerized environments, infrastructure code and stateless microservices can be redeployed within minutes. However, the heart of any Kubernetes cluster is its state database. In K3s, that state resides within the embedded etcd datastore (or SQLite in standalone single-server deployments). If control-plane disk corruption strikes, a cluster upgrade goes awry, or hardware fails without a verified backup, your entire cluster state—including deployments, custom resource definitions (CRDs), ingress routes, and persistent volume claims—is lost permanently.
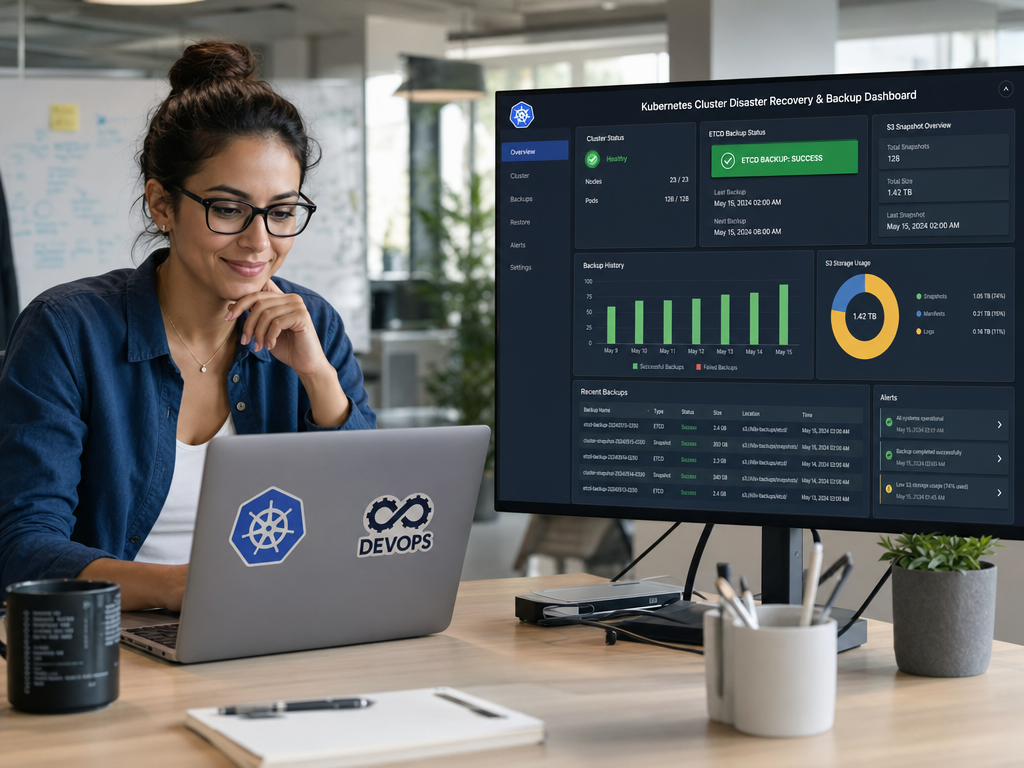
While many administrators periodically backup persistent volume data (as covered in our guide on Docker volume backups with Restic), backing up persistent volumes alone does not protect Kubernetes cluster topology. To achieve genuine disaster recovery resilience, you must automate regular etcd snapshots and stream them offsite to S3-compatible cloud storage.
In this comprehensive hands-on guide, you will learn how to configure automated etcd snapshots in K3s, securely authenticate with AWS S3 or MinIO object storage, trigger manual on-demand snapshots, inspect snapshot integrity, and execute a full cluster disaster recovery restore from scratch.
Understanding K3s etcd Snapshot Architecture
According to the Official K3s Backup & Restore Documentation, K3s includes a built-in etcd snapshot supervisor that manages point-in-time state captures without requiring external tools like etcdctl. When running a multi-server high-availability K3s cluster (or a single-server cluster configured with embedded etcd), the supervisor performs the following operations:
- Point-in-Time Consistency: It pauses write transactions momentarily to capture a deterministic binary snapshot of the bbolt database file.
- Local Storage Retention: Snapshots are saved by default to
/var/lib/rancher/k3s/server/db/snapshots/with configurable retention counts. - Automated S3 Uploads: When S3 integration is enabled, K3s immediately uploads the snapshot file over TLS to your specified S3 bucket and path prefix, ensuring that physical node failures do not destroy backup archives.
- Custom Cron Scheduling: K3s features a native cron expression engine to trigger backups during off-peak hours without relying on systemd timers or Linux crontab.
Prerequisites & Environment Setup
Before configuring snapshot automation, verify your environment meets these criteria:
- K3s Control-Plane Node: A running K3s server with embedded etcd (Ubuntu 22.04/24.04 or Debian 12).
- S3 Object Storage: An active bucket in AWS S3, Cloudflare R2, Wasabi, or a self-hosted MinIO instance.
- S3 Access Credentials: An IAM user or service key with read, write, and list permissions on the target bucket (
s3:PutObject,s3:GetObject,s3:ListBucket,s3:DeleteObject). - Root/Sudo Privileges: Full administrative access to the K3s host machine.
Step 1: Storing S3 Credentials Securely in K3s Configuration
While you can supply S3 parameters as command-line arguments to the K3s binary, best practice dictates defining them declaratively within the central K3s configuration file at /etc/rancher/k3s/config.yaml. This ensures settings persist across node reboots and service updates.
Create or open the configuration file with root privileges:
sudo mkdir -p /etc/rancher/k3s
sudo nano /etc/rancher/k3s/config.yaml
Append the declarative etcd snapshot configuration block. Replace placeholder values with your actual S3 endpoint, bucket, and credentials:
# Automated etcd S3 Snapshot Configuration
etcd-snapshot-schedule-cron: "0 */6 * * *"
etcd-snapshot-retention: 28
etcd-s3: true
etcd-s3-endpoint: "s3.eu-central-1.amazonaws.com"
etcd-s3-bucket: "k3s-cluster-backups-prod"
etcd-s3-folder: "etcd-snapshots"
etcd-s3-access-key: "AKIAIOSFODNN7EXAMPLE"
etcd-s3-secret-key: "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY"
etcd-s3-region: "eu-central-1"
etcd-s3-insecure: false
Here is what each parameter governs:
| Configuration Key | Functional Purpose |
|---|---|
| etcd-snapshot-schedule-cron | Standard 5-part cron syntax. 0 */6 * * * triggers every 6 hours. |
| etcd-snapshot-retention | Number of recent snapshots to retain. Old snapshots are pruned automatically. |
| etcd-s3-endpoint | S3 hostname. For MinIO or Ceph, set to your custom endpoint URL (e.g. minio.internal:9000). |
| etcd-s3-insecure | Set to false for valid TLS. Set to true only for internal HTTP MinIO testing. |
Restrict file access so unauthorized local users cannot read your S3 credentials:
sudo chmod 600 /etc/rancher/k3s/config.yaml
sudo systemctl restart k3s
Step 2: Triggering an On-Demand Manual Snapshot to S3
Never wait for the scheduled cron job to verify that your S3 credentials and bucket policies function properly. Trigger an immediate manual snapshot using the k3s etcd-snapshot subcommand:
# Trigger manual snapshot and upload to S3
sudo k3s etcd-snapshot save \
  --name "manual-pre-upgrade-snapshot" \
  --s3
Inspect the command output to verify successful execution:
INFO[0000] Snapshot manual-pre-upgrade-snapshot-k3s-master-01-1727784000 saved locally to /var/lib/rancher/k3s/server/db/snapshots/manual-pre-upgrade-snapshot-k3s-master-01-1727784000
INFO[0003] Uploading snapshot manual-pre-upgrade-snapshot-k3s-master-01-1727784000 to S3 bucket k3s-cluster-backups-prod
INFO[0006] Successfully uploaded snapshot to S3
Step 3: Listing and Inspecting Available Snapshots
K3s allows you to query both local disk snapshots and remote S3 objects directly from the terminal:
# List snapshots stored on remote S3
sudo k3s etcd-snapshot ls --s3
The output displays the snapshot name, creation timestamp, file size, and target S3 path:
Name                                                              Size        Created
manual-pre-upgrade-snapshot-k3s-master-01-1727784000              14.8 MiB    2026-10-01T10:00:00Z
etcd-snapshot-k3s-master-01-1727762400                            14.7 MiB    2026-10-01T04:00:00Z
etcd-snapshot-k3s-master-01-1727740800                            14.6 MiB    2026-09-30T22:00:00Z
Step 4: Executing a Full Cluster Disaster Recovery Restore
Now, let us walk through the complete disaster recovery scenario. In accordance with the Kubernetes etcd Disaster Recovery Architecture, restoring an etcd snapshot resets the cluster datastore to the exact commit state of the snapshot. Any resources created after the snapshot was taken will be rolled back.
Follow this exact operational sequence on the server node:
1. Stop the K3s control-plane service:
# Stop the control plane before modifying etcd state
sudo systemctl stop k3s
2. Execute the restore command pointing directly to your S3 snapshot:
# Restore cluster state directly from S3 snapshot
sudo k3s server \
  --cluster-reset \
  --cluster-reset-restore-path="manual-pre-upgrade-snapshot-k3s-master-01-1727784000" \
  --etcd-s3
The --cluster-reset flag performs several critical recovery actions:
- It moves existing corrupted or diverged etcd database files into a backup directory located at
/var/lib/rancher/k3s/server/db/etcd-old-TIMESTAMP/. - It downloads the requested snapshot directly from S3 into a temporary directory.
- It initializes a clean single-member etcd cluster initialized from that snapshot commit, generating fresh cluster tokens and consensus terms.
Once the terminal displays Managed etcd cluster membership has been reset, restart without --cluster-reset flag now, restart the systemd service:
sudo systemctl start k3sStep 5: Post-Restore Verification & Rejoining Worker Nodes
After restarting the control plane, verify that all core Kubernetes API services have recovered successfully:
# Verify node status
kubectl get nodes -o wide

# Check health of restored system pods
kubectl get pods -A
If your cluster includes multi-node workers (as deployed in our multi-node K3s cluster tutorial), worker nodes will automatically reconnect to the newly initialized control plane within 60 to 90 seconds. Their local k3s-agent processes re-establish secure TLS tunnel connections to port 6443 and resume container orchestration.
Automated Snapshot Pruning & Lifecycle Policies
While K3s prunes snapshots according to etcd-snapshot-retention, you can also leverage cloud-native S3 bucket lifecycle rules to achieve tiered storage cost optimization. For example, in AWS S3 or Wasabi, configure a lifecycle rule to transition snapshots older than 30 days to Glacier Flexible Retrieval, or delete snapshots permanently after 90 days.
{
  "Rules": [
    {
      "ID": "ExpireOldK3sSnapshots",
      "Status": "Enabled",
      "Filter": {
        "Prefix": "etcd-snapshots/"
      },
      "Expiration": {
        "Days": 90
      }
    }
  ]
}
Troubleshooting Common S3 Snapshot Errors
| Observed Error | Root Cause & Resolution |
|---|---|
| RequestError: send request failed (x509: certificate signed by unknown authority) | Occurs when connecting to self-hosted MinIO with self-signed SSL. Copy your CA cert to /usr/local/share/ca-certificates/ and run sudo update-ca-certificates. |
| AccessDenied: Access Denied | The IAM user lacks s3:PutObject or s3:ListBucket permissions on the designated folder prefix. |
| Snapshot file not found on S3 | Ensure etcd-s3-folder matches the exact directory path without leading slashes. Check with k3s etcd-snapshot ls –s3. |
Summary & Best Practices
Automating K3s etcd snapshots with offsite S3 replication guarantees that hardware breakdowns, configuration regressions, or operator errors never turn into catastrophic data loss events. By defining snapshot schedules declaratively in /etc/rancher/k3s/config.yaml, maintaining offsite S3 immutability, and routinely rehearsing cluster resets in a staging sandbox, your Kubernetes platform remains resilient and enterprise-ready.
Need assistance architecting bulletproof Kubernetes backup strategies or hardening your production cloud infrastructure? Explore our tailored IT and DevOps consulting services or contact our team for professional Kubernetes administration support.

Hi, I’m Mark, the author of Clever IT Solutions: Mastering Technology for Success. I am passionate about empowering individuals to navigate the ever-changing world of information technology. With years of experience in the industry, I have honed my skills and knowledge to share with you. At Clever IT Solutions, we are dedicated to teaching you how to tackle any IT challenge, helping you stay ahead in today’s digital world. From troubleshooting common issues to mastering complex technologies, I am here to guide you every step of the way. Join me on this journey as we unlock the secrets to IT success.